COMRAD: Cooperative multi-agent reinforcement learning from pixels.
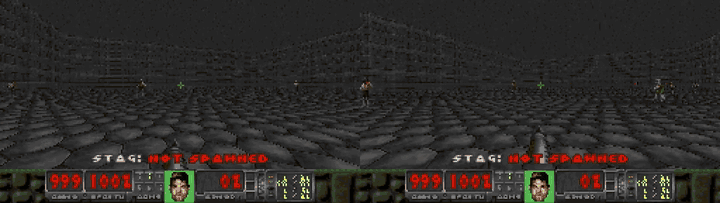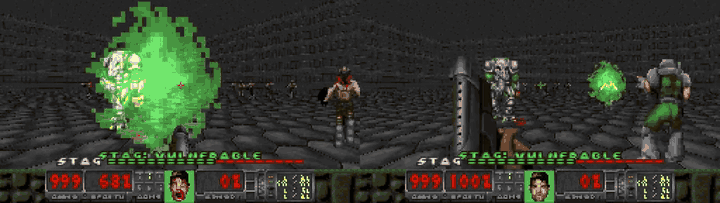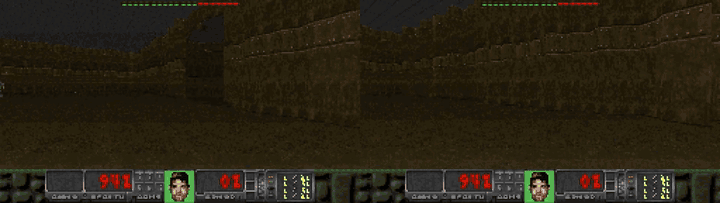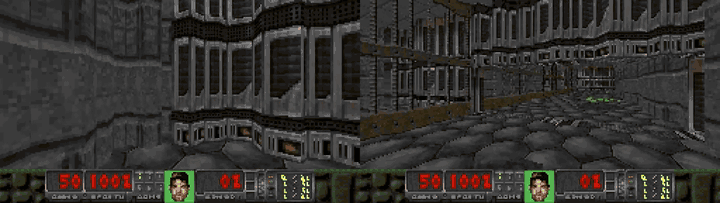
COMRAD is a benchmark of 13 first-person cooperative scenarios built on ViZDoom. Each scenario isolates one coordination skill: committing to a joint plan, synchronising in time, sharing a commons, swapping roles, or communicating without words.
pip install comrad-bench
import comrad

env = comrad.parallel_env("stag_hunt_arena")   # PettingZoo ParallelEnv
observations, infos = env.reset(seed=42)
while env.agents:
    actions = {agent: env.action_space(agent).sample() for agent in env.agents}
    observations, rewards, terminations, truncations, infos = env.step(actions)
Works with any MARL library that speaks PettingZoo or Gymnasium. No Sample Factory configuration is needed.
Scenarios
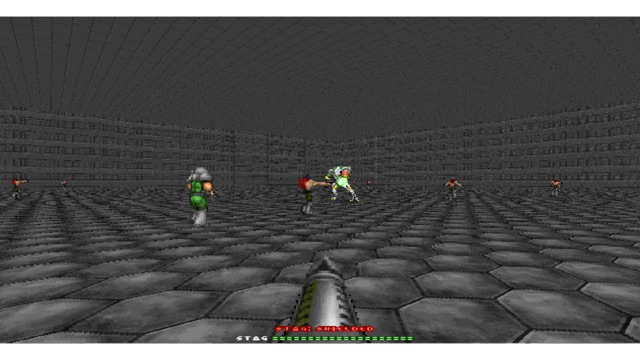 Stag Hunt Arena |
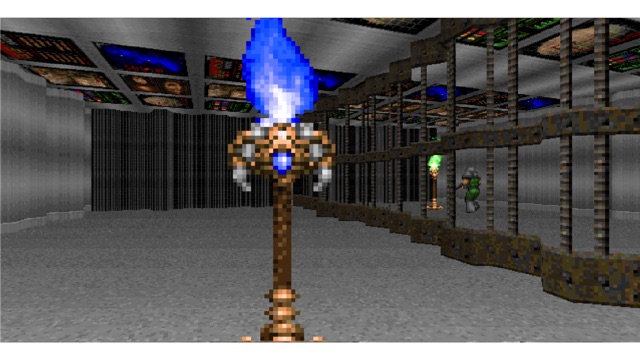 Rhythm Sync |
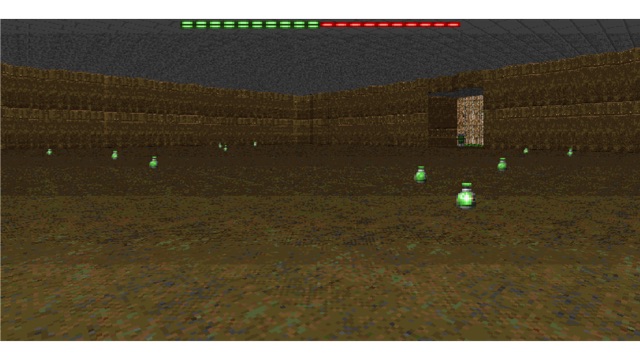 Foraging Commons |
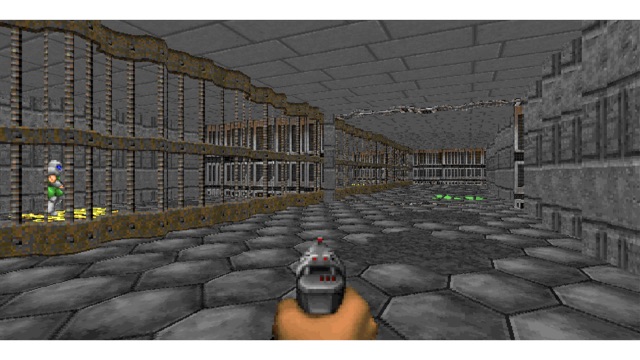 Co-op Puzzle |
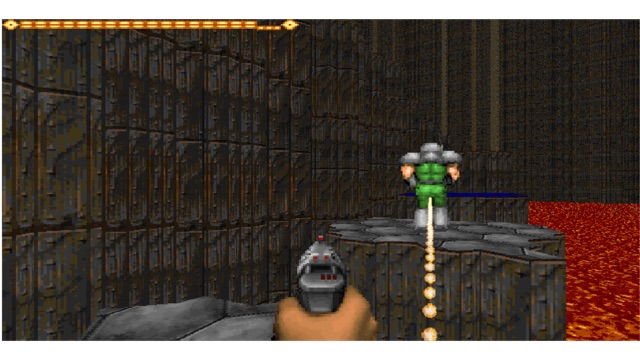 Platform Chain |
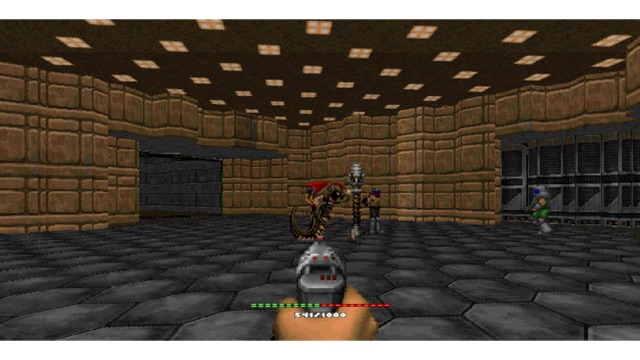 Armory Siege |
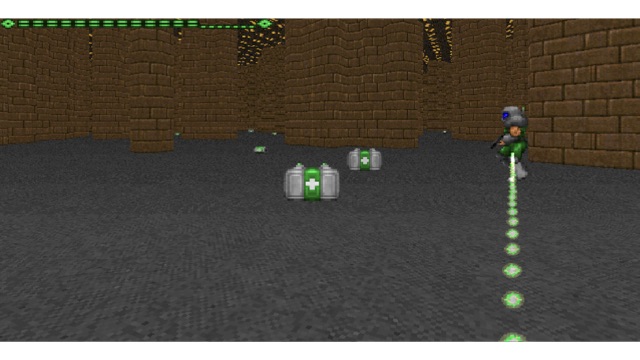 Co-op Health Gathering |
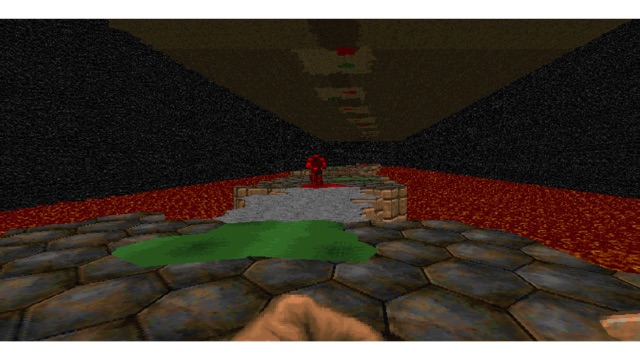 Lava Pit |
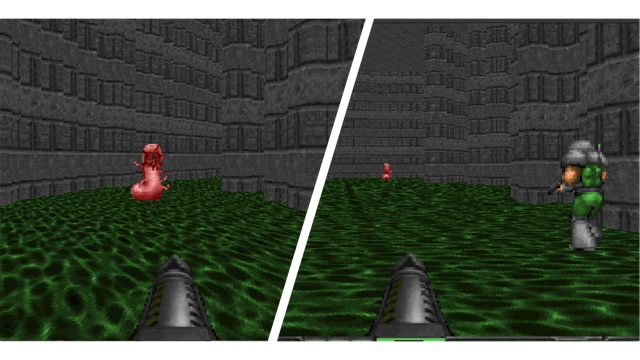 Smart / Dumb Enemies |
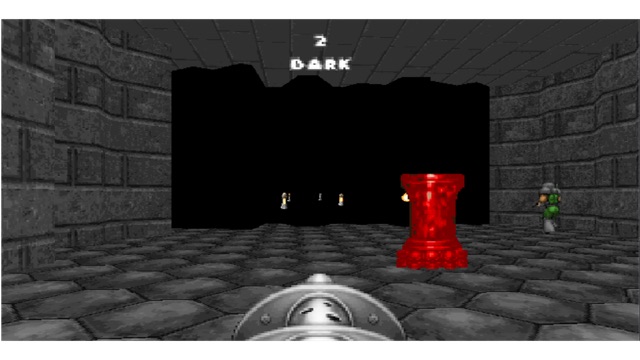 Stealth Labyrinth |
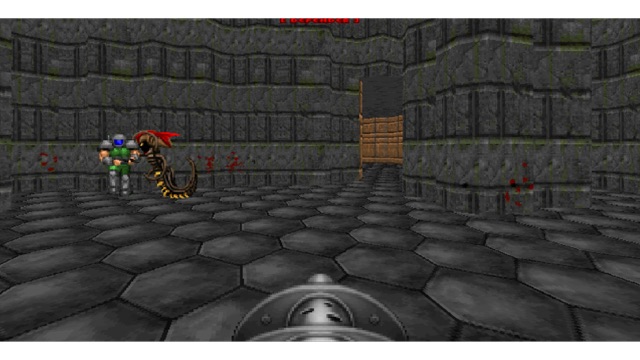 Ammo Carrier |
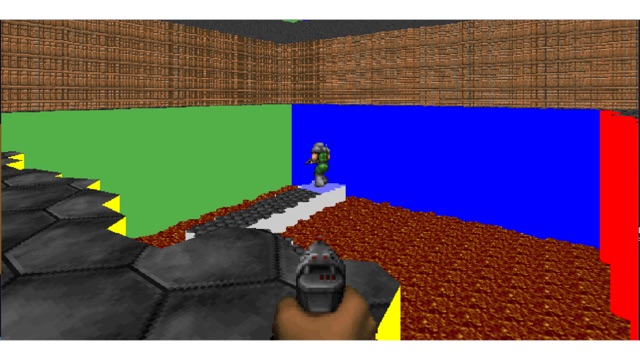 Lava Maze |
Where to next
- Installation and Quickstart: run a scenario in a minute.
- Scenarios: what each task tests and how it is scored.
- API reference: options, spaces, info keys and episode semantics.
- Sample Factory baselines: train IPPO, MAPPO, HAPPO, IDQN, VDN, QMIX or QPLEX with the bundled trainer.
- Baselines: results of the seven reference algorithms.
- Project page: playable demo, scoreboard and paper overview.