Smart Enemies
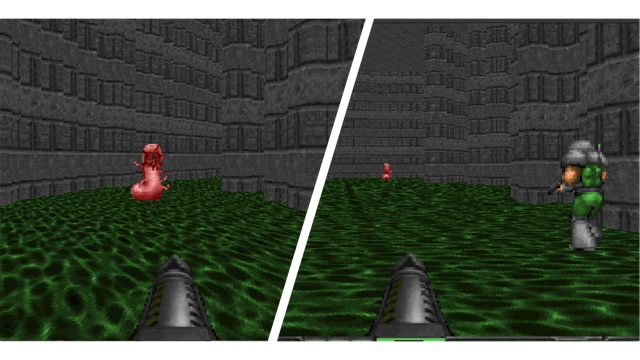
Players fight fleeing enemies that get harder to finish when several agents crowd the same target. Teams have to spread out instead of all chasing one enemy.
import comrad

env = comrad.parallel_env("smart_enemies")
| Gymnasium id | comrad/smart_enemies-v0 |
| Agents | 2 by default (supports 2–4) |
| Capability tested | Combat spacing, target prioritisation |
| Episode limit | 4500 steps |
| Observation | RGB image (72, 128, 3) per agent; measurement vector not available |
| Action space | Tuple(Discrete(3), Discrete(3), Discrete(3), Discrete(2)) |
Default shared_reward |
0.0: each agent receives its own reward |
Score (info["true_objective"]) |
Enemies killed |
Actions
Each agent sends one choice per head; index 0 is always "do nothing".
- move: none / forward / backward
- strafe: none / right / left
- turn: none / left / right
- attack: none / attack
Reward
Per agent: +5 per kill, bonuses for hits and health gained; penalties for health lost, death, ammo use and letting enemies flee.
The score in info["true_objective"] is what the benchmark reports. The shaped reward is only a training signal.
Variants
dumb_enemies: same arena, opposite density rule.