Dumb Enemies
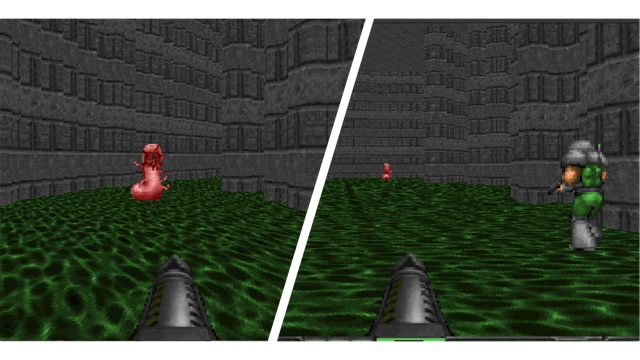
The same arena as Smart Enemies, with the density rule reversed: coordinated pressure makes enemies easier to corner, so converging on one target pays off.
import comrad

env = comrad.parallel_env("dumb_enemies")
| Gymnasium id | comrad/dumb_enemies-v0 |
| Agents | 2 by default (supports 2–4) |
| Capability tested | Cooperative pursuit, synchronised attacks |
| Episode limit | 4500 steps |
| Observation | RGB image (72, 128, 3) per agent; measurement vector not available |
| Action space | Tuple(Discrete(3), Discrete(3), Discrete(3), Discrete(2)) |
Default shared_reward |
0.0: each agent receives its own reward |
Score (info["true_objective"]) |
Enemies killed |
Actions
Each agent sends one choice per head; index 0 is always "do nothing".
- move: none / forward / backward
- strafe: none / right / left
- turn: none / left / right
- attack: none / attack
Reward
Per agent: +5 per kill, bonuses for hits, health gained and slowing enemies down; penalties for health lost, death and ammo use.
The score in info["true_objective"] is what the benchmark reports. The shaped reward is only a training signal.
Variants
smart_enemies: same arena, opposite density rule.